44 pages, 7 questions
| Source | Answer | Match |
|---|---|---|
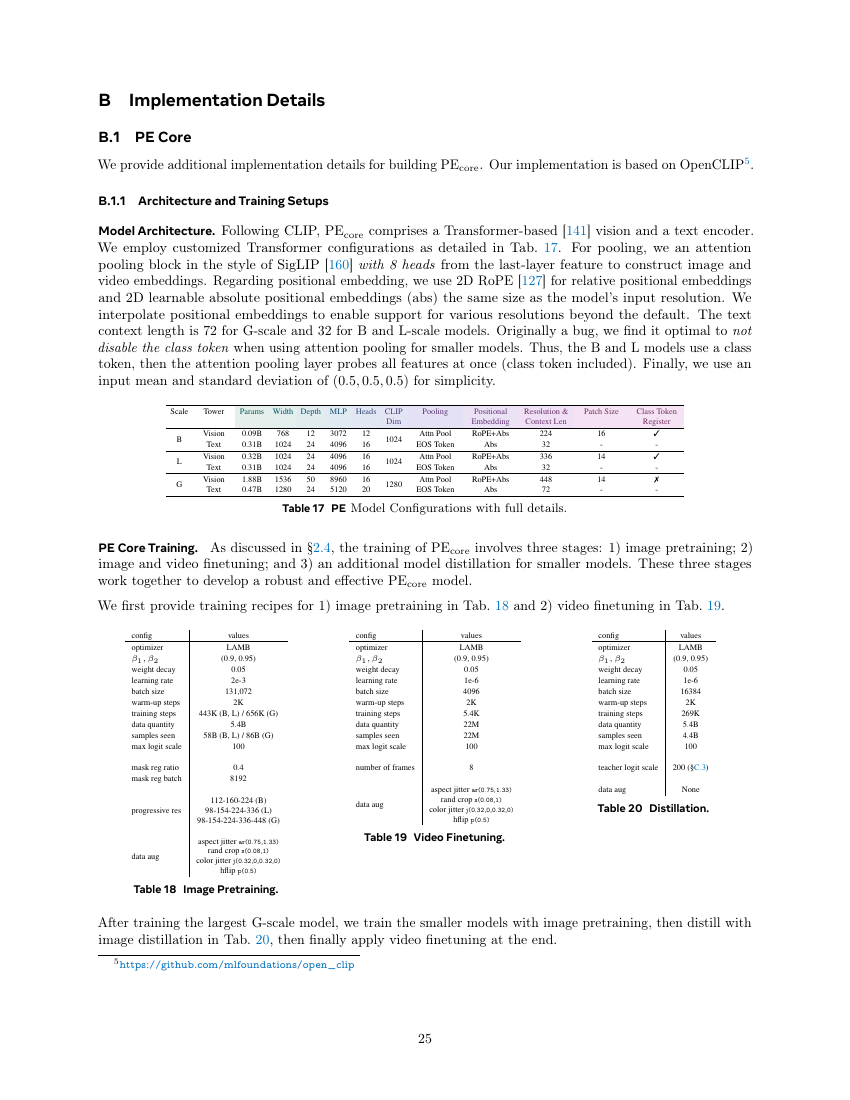
| Target | 17 | |
| gemini | Unknown | ✗ |
| luna | 17 | ✓ |
| Source | Answer | Match |
|---|---|---|
| Target | qwen | |
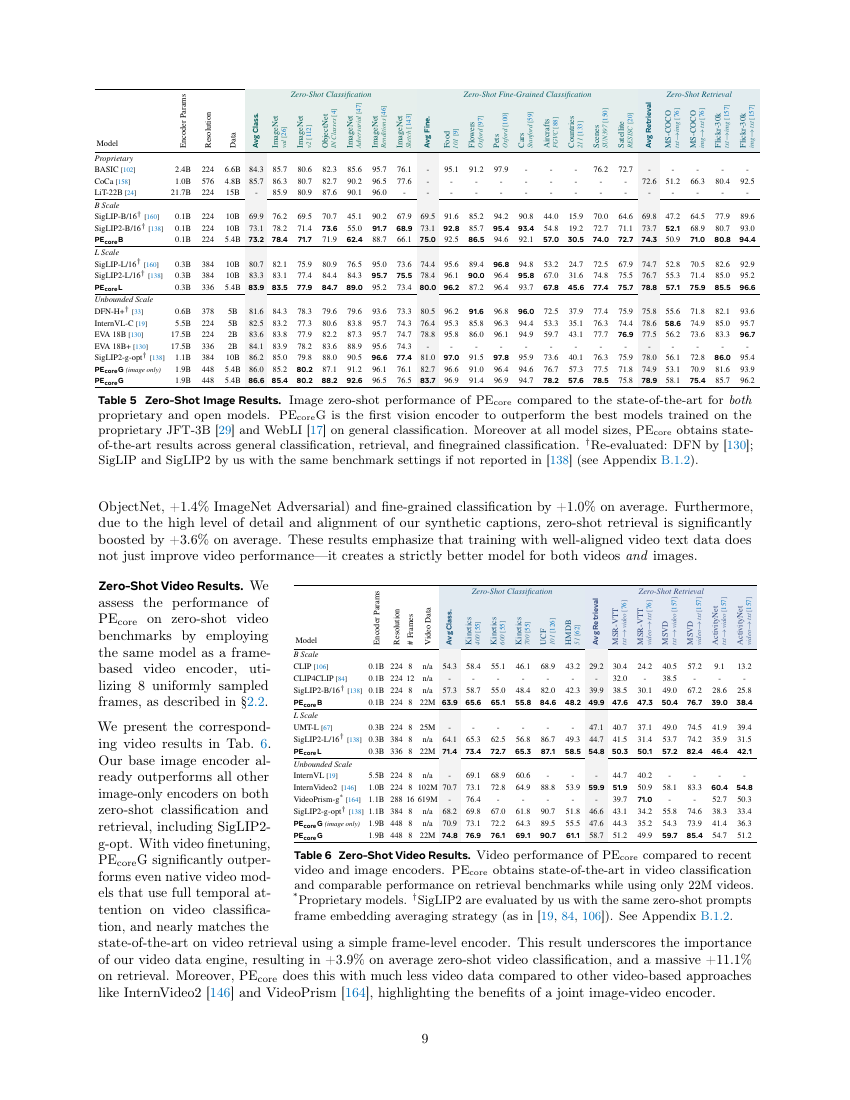
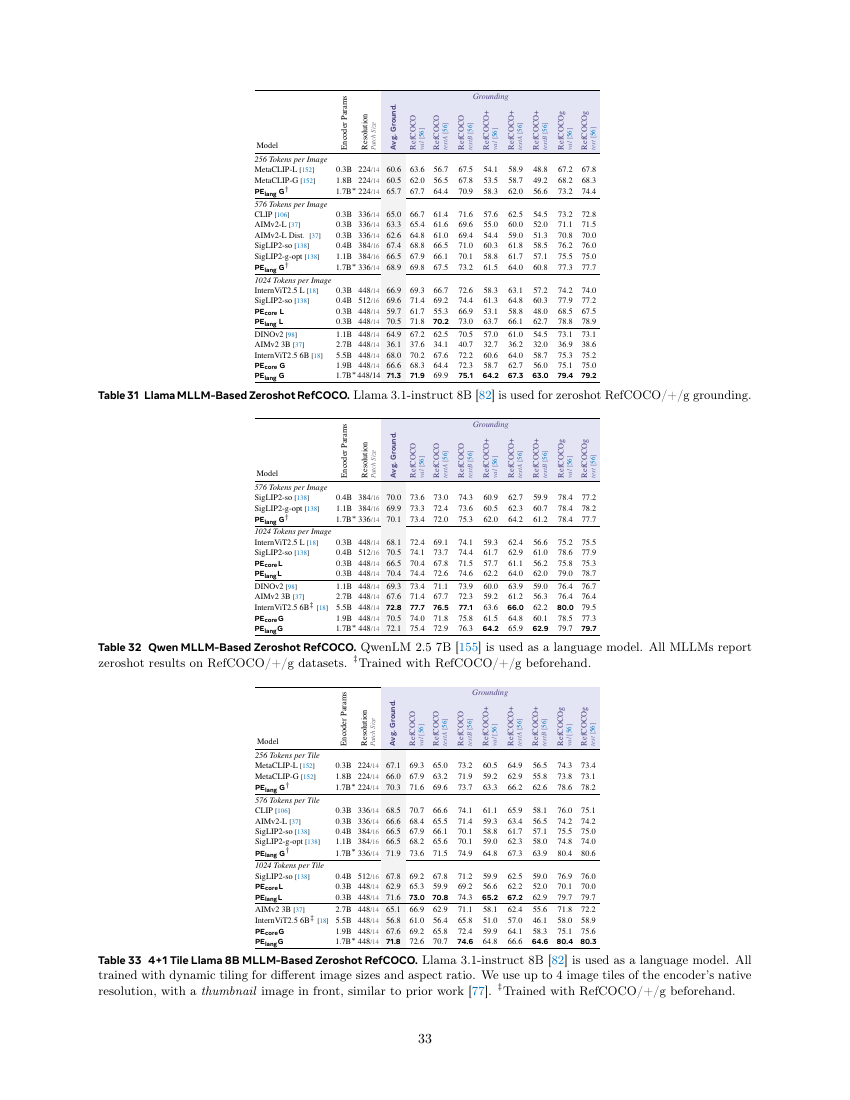
| gemini | 1. **Search Strategy:** The user is asking for a "family of models" used for comparisons involving "native resolution". I will scan the document for the keywords "native resolution" and "comparison" to find the relevant model family. 2. **Locating Information:** * On page 33, in the appendix, I find Table 33. * The caption for Table 33 reads: "Table 33 4+1 Tile Llama 8B MLLM. Llama 3.1-Instruct 8B is used as a language model. All trained with dynamic tiling for different image sizes and aspect ratio. We use up to 4 image tiles of the encoder’s **native resolution**, with a thumbnail image in front, similar to prior work [77]." * This caption explicitly links the model family "MLLM" (Multimodal Large Language Models) with the use of "native resolution" for processing images. The table itself is a comparison of different models within this family. 3. **Extraction and Formatting:** * The family of models is "MLLMs". * This is a single answer, so no list formatting is needed. * The answer does not contain numbers, units, percentages, or dates, so no special formatting is required. * The final answer should be just the model family name. FINAL ANSWER: MLLMs | ✗ |
| luna | Vision encoders | ✗ |
| Source | Answer | Match |
|---|---|---|
| Target | Unknown | |
| gemini | pairwise feature cosine similarity | ✗ |
| luna | cosine similarity | ✗ |
| Source | Answer | Match |
|---|---|---|
| Target | 76 | |
| gemini | 76 | ✓ |
| luna | 76 | ✓ |
| Source | Answer | Match |
|---|---|---|
| Target | 99 | |
| gemini | 1. The "Related Work" section is section 6, which begins on page 20. 2. The page immediately before the "Related Work" section is page 19. 3. The question asks for the first citation number used in the main text of this page, excluding figure/table captions. 4. Scanning the main text of page 19, the first paragraph under the heading "5.3 Comparison with Existing Vision Encoders" begins: "Frozen Feature Dense Prediction. In Tab. 13, we compare different vision encoder’s frozen features on three dense prediction tasks: DAVIS tracking [104]...". 5. The first citation number encountered in the main text is 104. FINAL ANSWER: 104 | ✗ |
| luna | 99 | ✓ |
| Source | Answer | Match |
|---|---|---|
| Target | Unknown | |
| gemini | Unknown | ✓ |
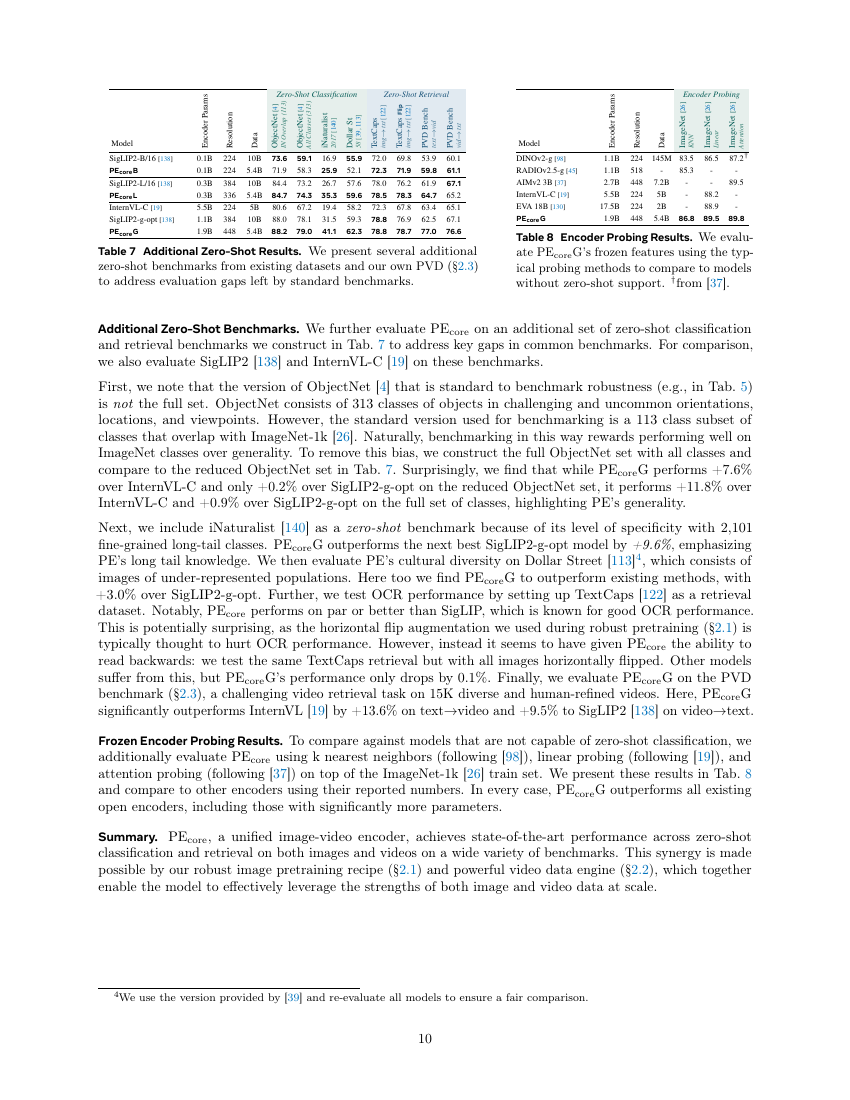
| luna | 61.1 | ✗ |
| Source | Answer | Match |
|---|---|---|
| Target | early layers in CLIP possess good spatial understanding | |
| gemini | Unknown | ✗ |
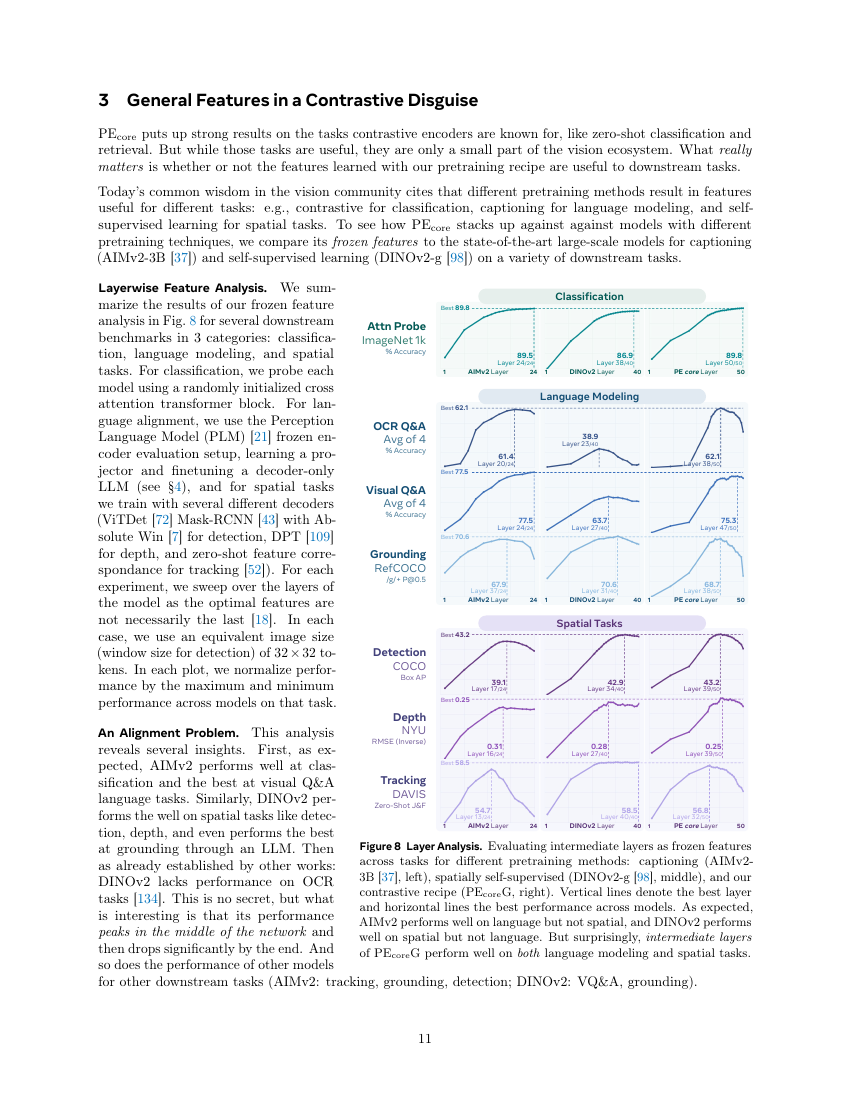
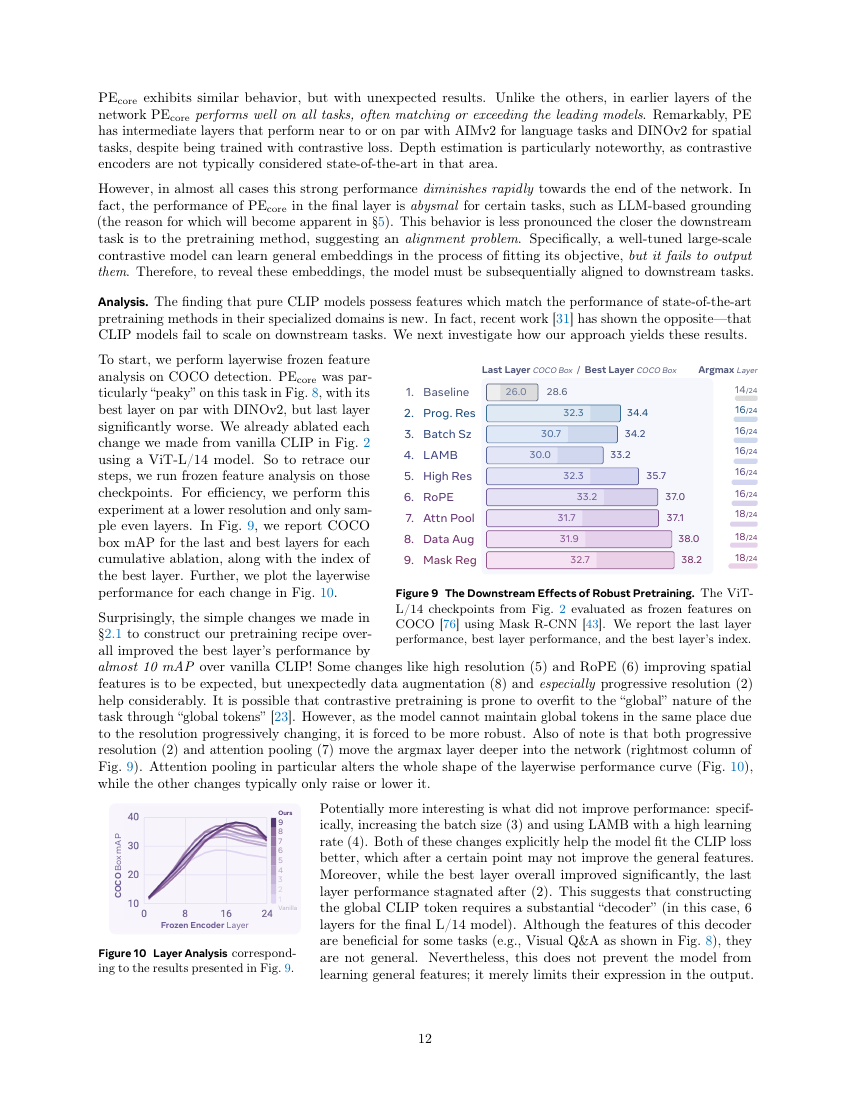
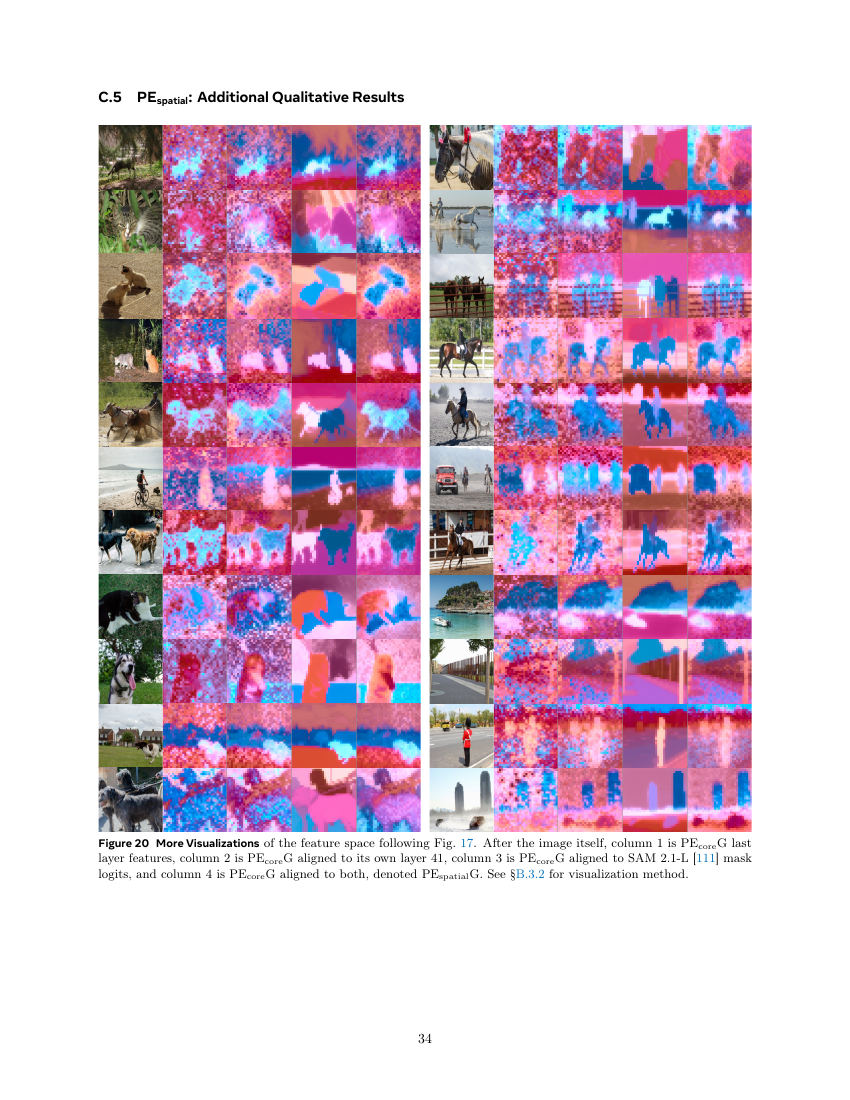
| luna | early layers in CLIP possess good spatial understanding | ✓ |